Why feature request authenticity suddenly matters
Product teams have always dealt with noisy input: duplicate ideas, vague “please add X,” or highly opinionated asks that don’t represent real demand. What’s changed is the speed and volume at which feedback can be produced. AI assistants, copy-paste templates, and community “prompt packs” can generate credible-sounding feature requests at scale. The risk isn’t that these requests are malicious; it’s that they look structured enough to win attention and end up skewing prioritization.
A practical way to respond is to treat authenticity like any other quality signal. A “Feedback Authenticity Score” doesn’t try to police users or “catch” them. It helps your team route, weight, and validate incoming requests before they influence roadmap scoring, revenue impact models, or stakeholder narratives.
What the Feedback Authenticity Score is
The Feedback Authenticity Score is a lightweight framework that assigns each feature request a confidence rating based on measurable signals. The output is not a binary verdict (real vs. fake). It’s a score that informs how much verification a request needs before it affects prioritization.
In practice, you use the score to:
- Identify likely AI-generated or template-based requests early.
- Prevent one “perfectly written” request from outweighing multiple messy but genuine ones.
- Route low-confidence items into clarification workflows instead of roadmap scoring.
- Reduce downstream churn from building features with weak real-world backing.
A practical scoring model you can implement this week
Keep the model simple: 0–100 points, composed of a few signal groups. Most teams can start with 5–7 signals and refine over time.
1) Identity and relationship signals (0–30 points)
These signals estimate whether the requester is a known, consistent human in your ecosystem.
- Account maturity: tenure, verified domain, SSO membership, or historical activity.
- Cross-system consistency: same email/domain appears in CRM, support, or billing.
- Prior feedback pattern: has the user commented, voted, or followed up before?
High score doesn’t mean the request is correct—only that it’s likely tied to a real user context.
2) Behavioral submission signals (0–15 points)
AI and templates tend to create repeatable timing and interaction patterns:
- Speed anomalies: long, polished request submitted seconds after signup.
- Burstiness: multiple requests from one user/account in a short window.
- Engagement depth: request submitted without reading existing items or searching.
3) Text structure and specificity signals (0–25 points)
This is where teams often over-index. Use it, but keep it bounded.
- Use-case concreteness: includes workflow, constraints, environment, and success criteria.
- Natural imperfection: real users have partial context, shorthand, and inconsistencies.
- Template fingerprints: repeated headings, identical phrasing across many requests, “generic persona” language.
A strong indicator of authenticity is not “good writing.” It’s verifiable operational detail (roles, permissions, integrations, edge cases, data volume, compliance constraints) that matches what the product actually does.
4) Duplicate and similarity signals (0–20 points)
Similarity isn’t bad—popular requests will look alike. What you’re watching for is unnatural clustering:
- High similarity to many unrelated requests: suggests a shared template.
- Near-duplicates with different accounts: could be AI regeneration of the same idea.
- Semantic collisions in retrieval: if your dedupe relies on embeddings, collisions can falsely group unrelated items or miss true duplicates. If that’s happening, it’s worth addressing the underlying retrieval quality before you treat similarity as an authenticity signal. (Related: detecting and fixing vector embedding collisions in LLM retrieval.)
5) Follow-up responsiveness signals (0–10 points)
One of the most reliable authenticity checks is what happens after you ask a question.
- Clarification rate: does the requester answer within a reasonable time?
- Answer quality: do they provide real screenshots, logs, constraints, or examples?
- Consistency under probing: do details stay coherent when you ask “when/where/how often?”
How to use the score without creating user friction
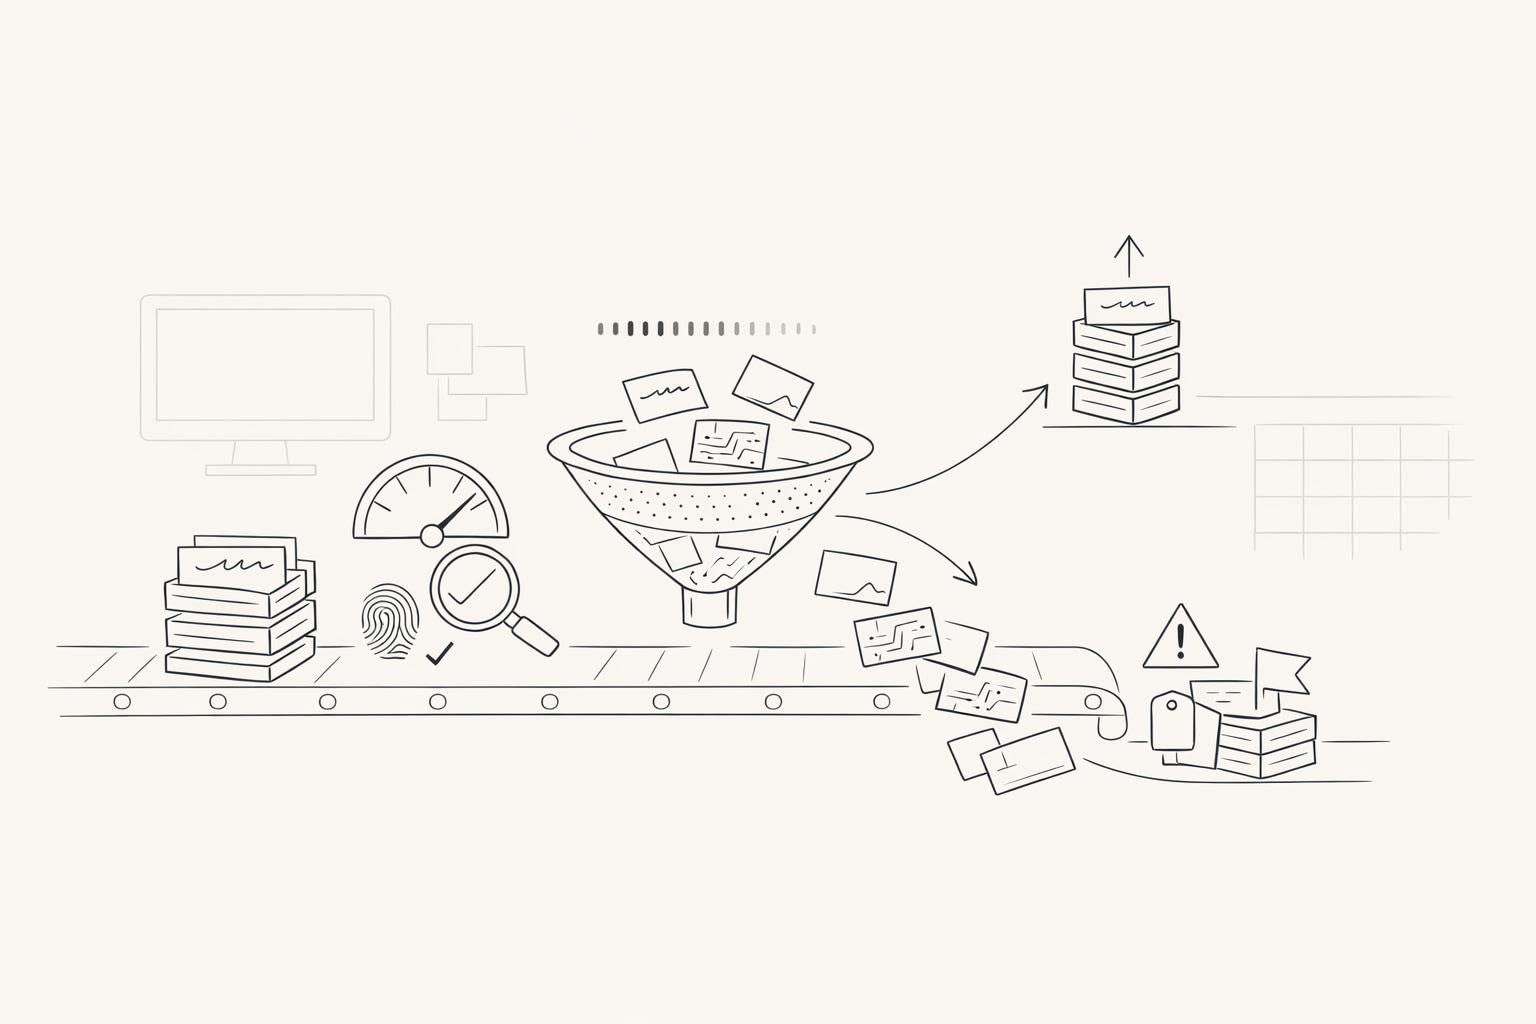
The scoring only matters if it changes workflow in a sensible way. A simple three-lane approach works:
- 80–100 (High confidence): eligible for normal dedupe, tagging, segment weighting, and prioritization scoring.
- 50–79 (Medium confidence): eligible, but requires one clarifying question before it influences roadmap scoring.
- 0–49 (Low confidence): route to triage; do not let it affect prioritization until verified.
This is where a central feedback system helps. In canny.io, teams can centralize requests, deduplicate, and keep a clean audit trail of comments and follow-ups, which makes it easier to apply authenticity-driven routing without losing legitimate signals from quieter customer segments.
Designing clarifying questions that expose templated requests
Low-confidence requests should trigger a short, respectful “use-case confirmation” sequence. The goal is to confirm context, not interrogate the user.
- Ask for a concrete scenario: “What’s the last time you tried to do this? What blocked you?”
- Ask for constraints: “Is this for a single workspace or multiple? Any security/compliance requirements?”
- Ask for impact measurement: “What would success look like—time saved, fewer errors, higher conversion?”
Template-based requests often collapse here: they can restate the feature, but can’t supply operational context. Genuine requests usually become more useful after one question.
Preventing authenticity issues from contaminating prioritization
The biggest failure mode is letting low-confidence requests flow into “demand metrics” as if they were equivalent to validated customer pain. To avoid that:
- Separate raw volume from validated demand: track “requests received” and “requests confirmed.”
- Weight by segment with safeguards: enterprise accounts or strategic segments may need less volume to be meaningful, but still require confirmation.
- Make scoring transparent internally: show the lane and the key signals that drove it so stakeholders don’t treat it as a black box.
If you already route feedback by customer segment and product area, add authenticity as an additional routing dimension so low-confidence items go to a clarification queue rather than to roadmap discussions. (Related: feedback routing matrix for auto-assigning feature requests by segment and product area.)
Operational guardrails for AI-assisted feedback intake
Many teams now use AI to summarize conversations from support or sales, which is different from AI inventing requests. Guardrails help you benefit from automation without amplifying noise:
- Label AI-originated entries: distinguish “summarized from conversation” vs. “user-submitted.”
- Store provenance: link back to the ticket, call snippet, or email thread that generated the idea.
- Require at least one human corroboration: before an AI-captured request influences prioritization, it should be validated by a real user interaction or existing evidence.

What to measure to keep the score honest
Finally, treat the framework like a product metric. Track:
- False positives: legitimate users flagged low-confidence (reduce friction here).
- False negatives: templated/AI requests that still influenced prioritization.
- Time-to-validation: how quickly medium/low-confidence requests become confirmed or closed.
- Outcome alignment: whether high-confidence requests correlate with adoption and retention post-release.
The intent is not to “ban AI,” but to ensure your prioritization reflects real customer pain and real customer value—especially when the input stream is increasingly easy to manufacture.